In recent years, Transformers with multimodal pre-training have made significant progress in visually rich document understanding. However, existing models mainly focus on features such as text and vision, and ignore the importance of layout relationships between text nodes. This paper proposes a novel document understanding model, GraphLayoutLM, which uses layout structure graph modeling to inject document layout knowledge into the model. GraphLayoutLM uses a graph reordering algorithm to adjust text sequences based on the graph structure. In addition, the model in this paper uses a layout-aware multi-head self-attention layer to learn document layout knowledge. The model can understand the spatial arrangement of text elements and improves document understanding.
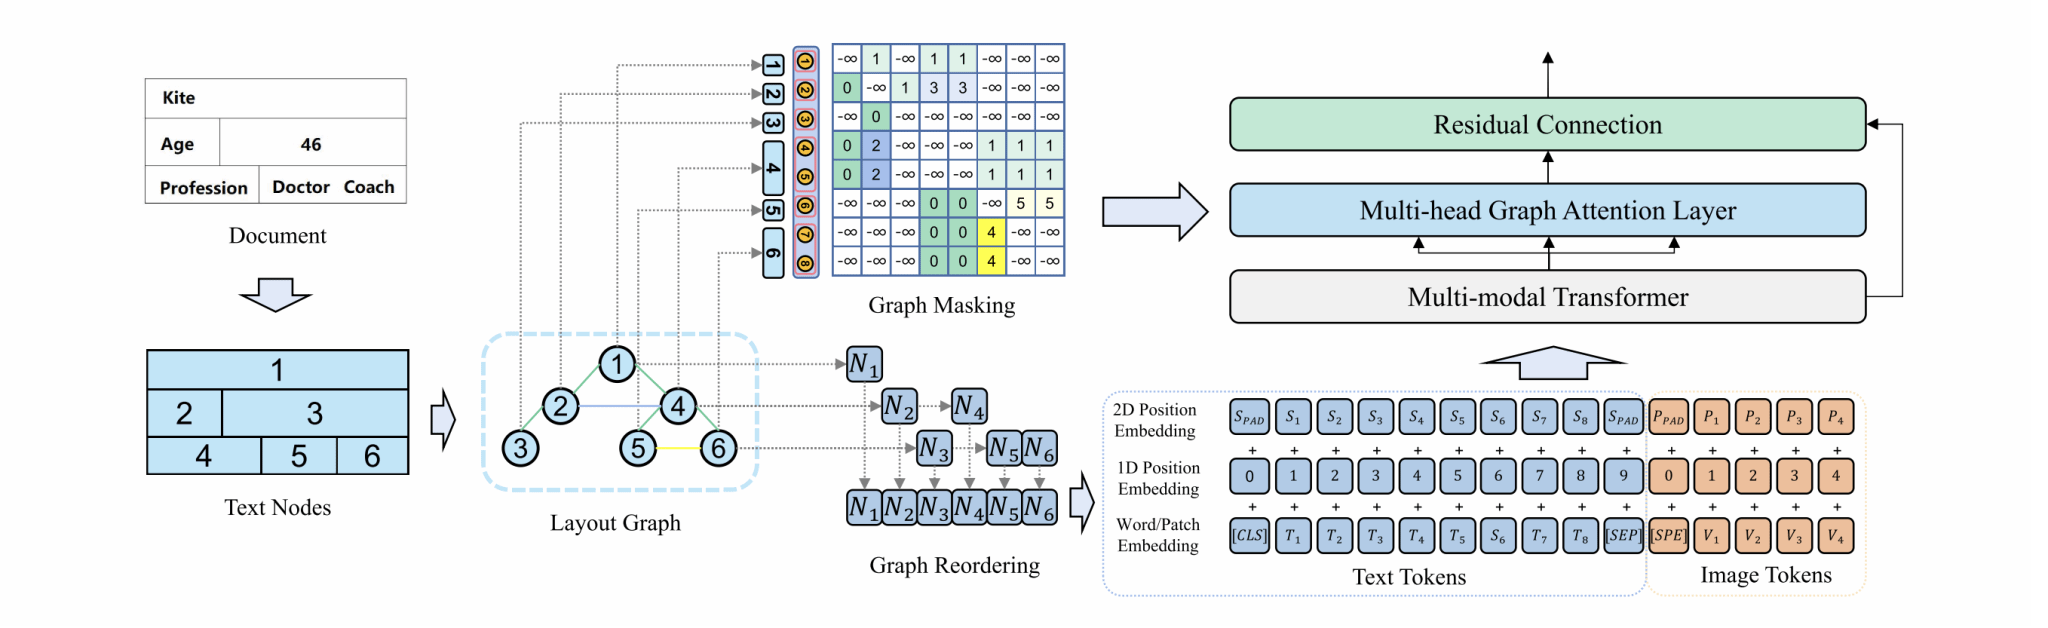
Figure 1. GraphLayoutLM Architecture
This research evaluated the model on multiple benchmark datasets, including FUNSD, XFUND and CORD, and achieved state-of-the-art results on these datasets. The experimental results show that the proposed method clearly improves on existing methods and demonstrates the importance of incorporating layout information into document understanding models. In addition, ablation experiments were conducted to study the contribution of each component of the model. The results show that the graph reordering algorithm and the layout-aware multi-head self-attention layer play a crucial role in achieving the best performance. This research was funded by the National Natural Science Foundation of China, the Natural Science Foundation of Hubei Province, the Fundamental Research Funds for the Central Universities and other projects.
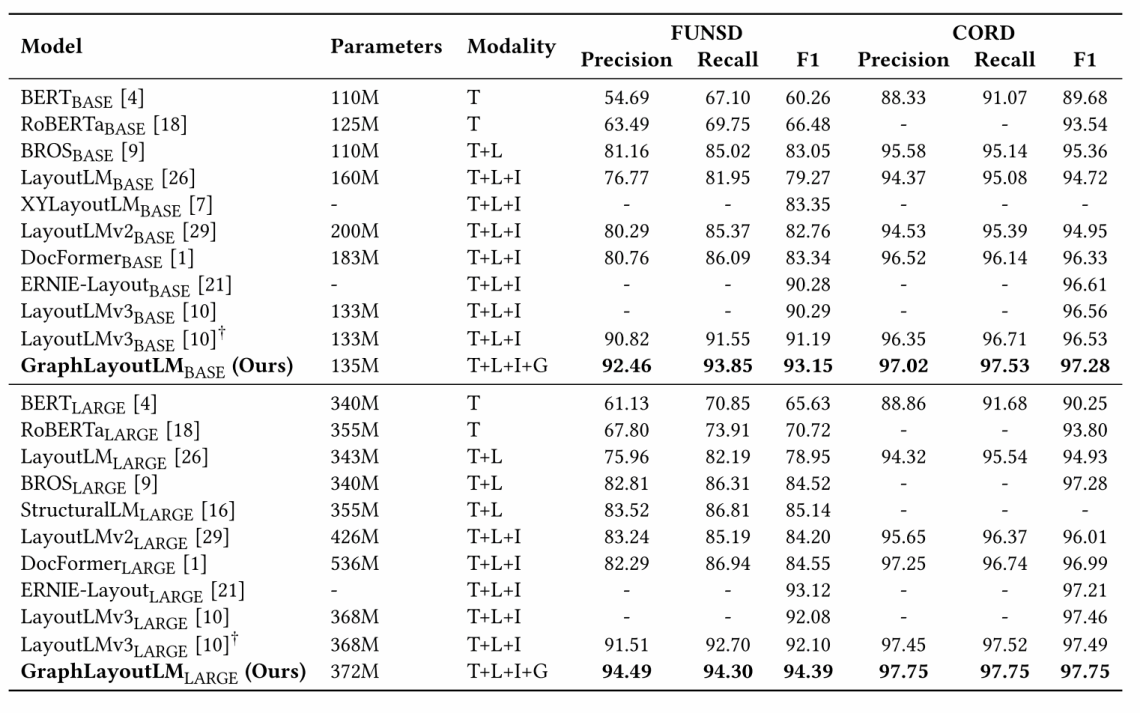
Figure 2. Results on the FUNSD and CORD Test Sets