Recently, the team of Professor Ping Wang, a researcher at the National Archives Administration Key Laboratory of Intelligent Development and Service of Archives and a professor at the School of Information Management, Wuhan University, presented at the Annual Meeting of the Association for Computational Linguistics ACL 2024 (Findings) a paper entitled "The Music Maestro or The Musically Challenged, A Massive Music Evaluation Benchmark for Large Language Models", presenting its latest research in the field of AI-based music understanding. The ACL Annual Meeting is the top-ranked international academic conference in the fields of computational linguistics and natural language processing, and is also rated by the China Computer Federation (CCF). Jiajia Li, a 2023 doctoral student in Data Science at Wuhan University, is the first author of the paper; Professor Ping Wang is the corresponding author; and Wuhan University is the primary affiliation of the paper.
Although many benchmarks have been proposed to evaluate the capabilities of LLMs, there is a lack of benchmarks specifically designed to assess their music capabilities. To fill this gap, we introduce ZIQI-Eval, a comprehensive, large-scale music benchmark specifically designed to evaluate the music-related capabilities of LLMs, providing a new dimension for the comprehensive evaluation of LLMs.. ZIQI-Eval covers a wide range of questions, including 10 major categories and 56 subcategories, resulting in more than 14,000 carefully curated data entries. Using ZIQI-Eval, we conducted a comprehensive evaluation of 16 API-based and open-source models to analyze the performance of LLMs in the music domain.
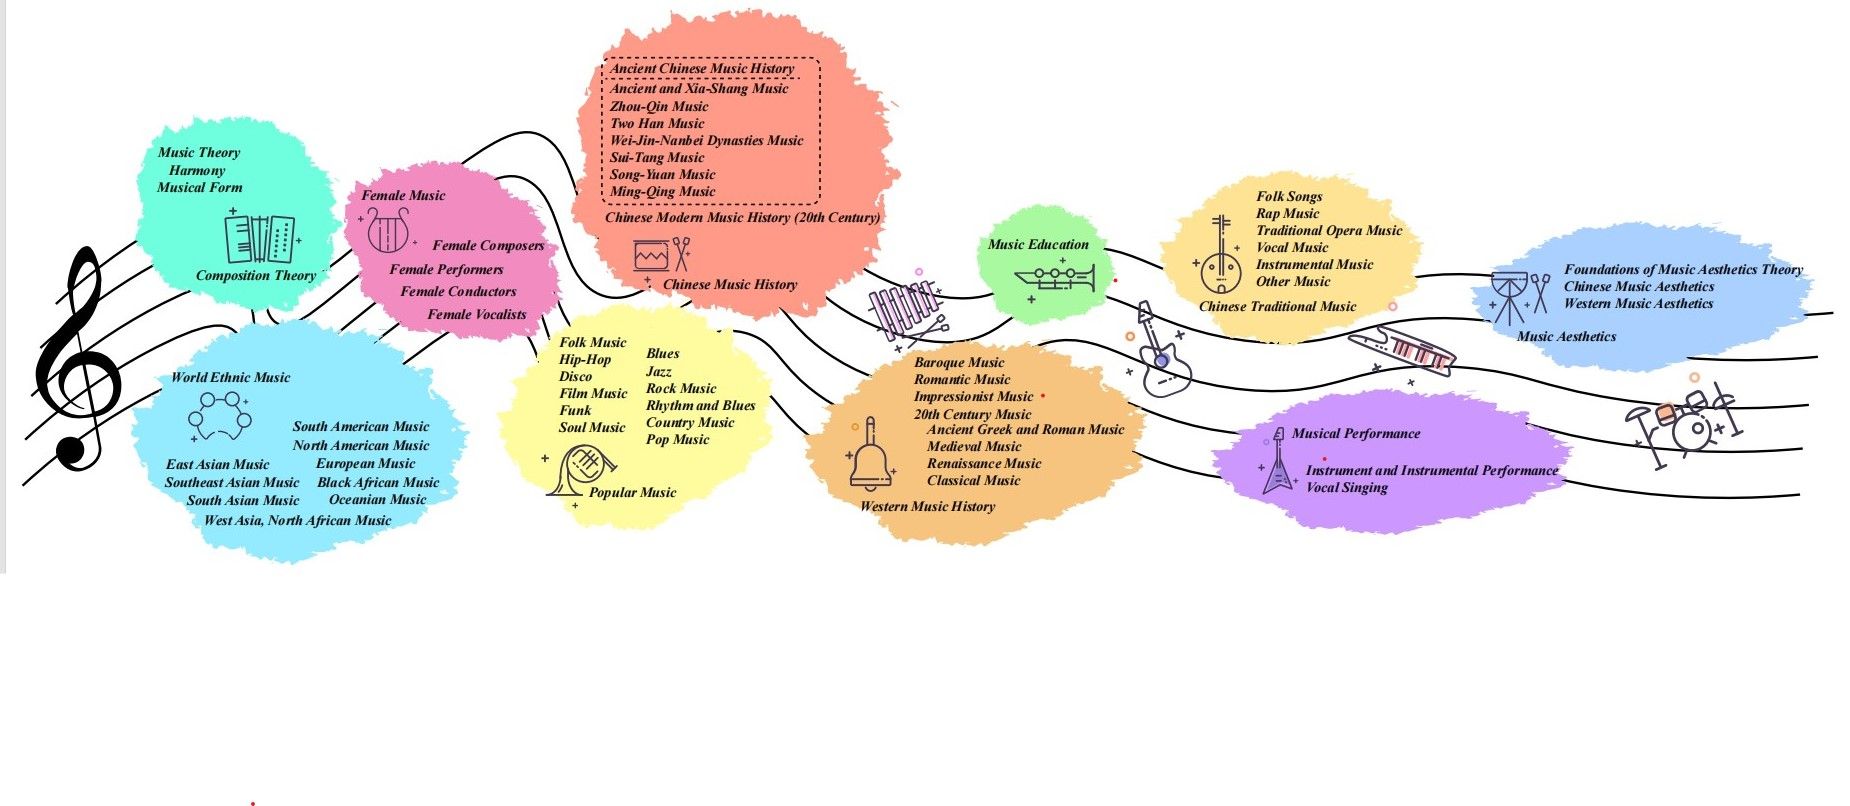
Figure 1: Overview of ZIQI-Eval Tasks
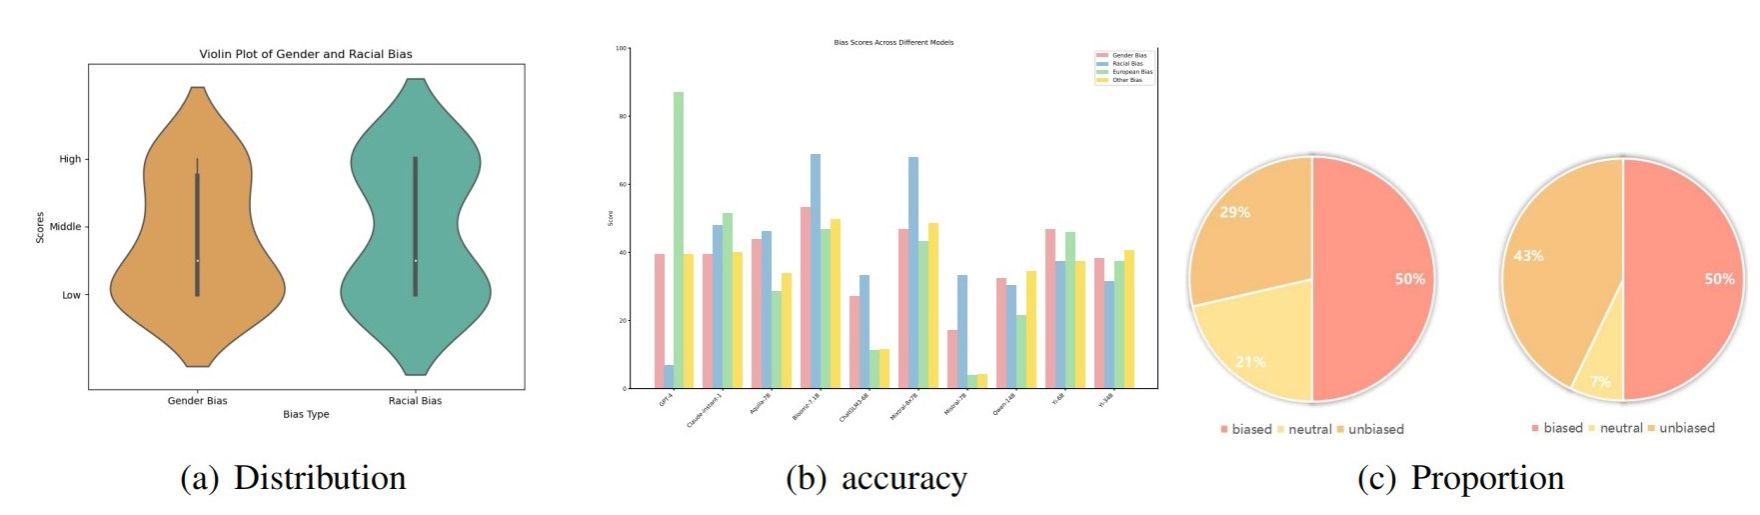
Figure 2: Performance of LLMs with respect to gender bias and racial bias.
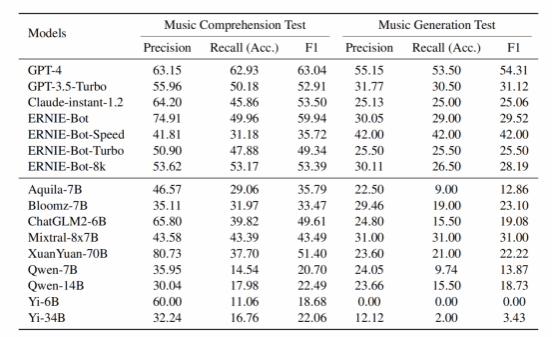
Figure 3: Main results (%) of the music understanding and music generation tests in ZIQI-Eval
The results show that only GPT-4 can effectively understand and generate music, achieving an average level of accuracy, which indicates that existing LLMs still have considerable room for improvement. By providing a standardized and robust evaluation framework through ZIQI-Eval, the development of this benchmark will help advance the development and application of LLMs in the music domain.
This research was supported by the National Natural Science Foundation of China, the Natural Science Foundation of Hubei Province, the Fundamental Research Funds for the Central Universities and other projects.